My research focuses on learning from imperfect real-world data with reinforcement learning. Robot data in the real world is largely imperfect, including suboptimal demonstrations, autonomous policy rollouts during deployment, and failure data, and robots should learn at scale from this full spectrum of real-world experience. Towards this goal, I work on various aspects of robotics and reinforcement learning, with a current focus on stable and scalable off-policy RL algorithms for pre-training robotic foundation models. I am fortunate to be advised by professor Sergey Levine at UC Berkeley. During my undergrad I was advised by professors George Konidaris and Michael Littman at Brown. Please check out my selected work below.
Google Scholar | Github | Twitter
Publications
|
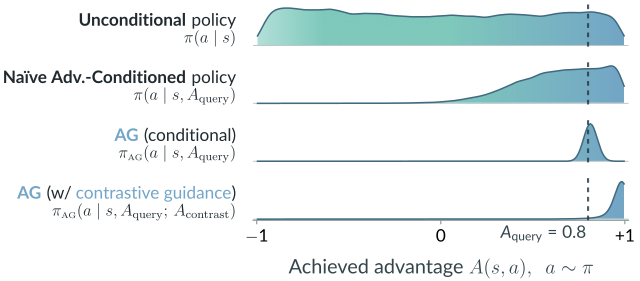
Reinforcement Learning via Advantage Guidance Zhiyuan Zhou, Sergey LevinearXiv preprint, 2026 [website] [paper] [code] We introduce Advantage Guidance, a new RL algorithm that trains with a simple supervised learning loss conditioned on advantages, yet outperforms strong RL methods. The key is to make the policy genuinely responsive to advantage conditioning, then use contrastive diffusion guidance at sampling time for advantage maximization. |
|
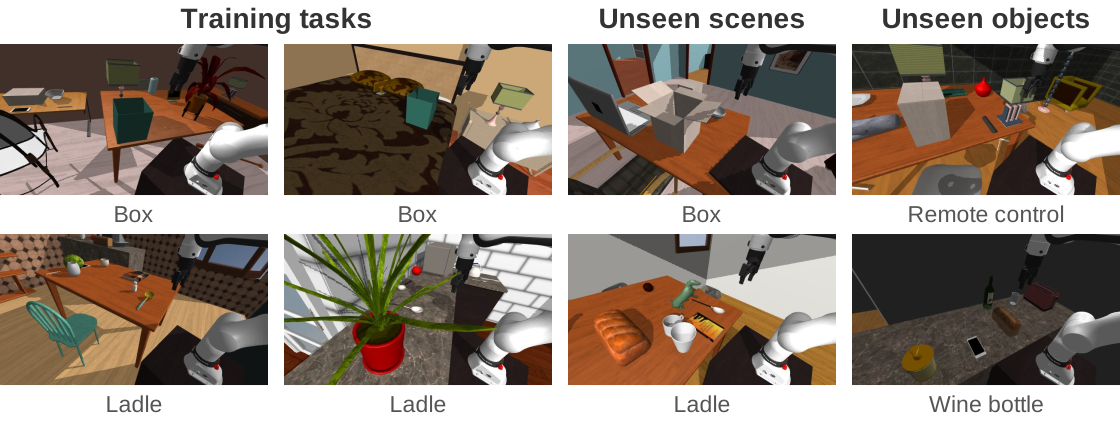
Reinforcement Learning Enables Scaling Generalist Robot Policy Improvement Michal Korniak*, Marco Bagatella*, Ralf Römer*, ..., Zhiyuan Zhou, ..., Max Simchowitz, Andrew WagenmakerarXiv preprint, 2026 [website] [paper] [code] RL leads to generalist policy improvement: when trained on a sufficiently broad task distribution, it improves performance on unseen scenes and objects. |
|
|
Robotic Data Inoculation Qiyang Li, Zhiyuan Zhou, Charles Xu, Sergey LevinearXiv preprint, 2026 [website] [paper] We introduce Data Inoculation, a robot data collection method that combines closed-loop human teleoperation with learned perturbations from an online RL residual policy. RL introduces mistakes a learned policy might make, and human corrections provide recovery demonstrations, improving data coverage and training more robust robot policies. |
|
|
Value Forcing: Aligning Return Distributions at All Noise Levels Chongyi Zheng, Zhiyuan Zhou, Qiyang Li, Benjamin Eysenbach, Sergey LevinearXiv preprint, 2026 [website] [paper] [code] Value Forcing is a way to learn distributional value functions with flow matching, and the key is to enforce Bellman consistency at every noise level. This provides richer supervision for value learning and improves performance, especially with little data. |

|
Test-Time Gradient Guidance of Flow Policies in Reinforcement Learning Zhiyuan Zhou, Andy Peng, Charles Xu, Qiyang Li, Jost Tobias Springenberg, Kevin Frans, Sergey LevineNeurIPS, 2026 [website] [paper] [code] We propose QGF (Q-Guided Flow), an RL algorithm that performs policy optimization entirely at test time. QGF trains a reference flow policy with BC and a TD-based critic, then uses a novel critic gradient estimator to guide the flow policy toward higher-value actions without any additional policy learning. |
|
|
\(\pi^{*}_{0.6}\): a VLA that Learns from Experience Ali Amin, Raichelle Aniceto, ..., Zhiyuan ZhouRobotics Science and Systems (RSS), 2026. [website] [paper] We train a VLA with offline RL through advantage conditioning, enabling the VLA to consume all robotic data, including suboptimal automonous trajectories and on-policy expert interventions. This doubles the task throughput and halves the failure rate on many challening long-horizon tasks, and enables long deployment time (13h) without failure. |
|
|
Robust Finetuning of Vision-Language-Action Robot Policies via Parameter Merging Yajat Yadav*, Zhiyuan Zhou*, Andrew Wagenmaker, Karl Pertsch, Sergey LevineInternational Conference on Learning Representations (ICLR), 2026 [website] [paper] [code] Finetuning generalist policies easily overfits. Turns out that simply merging the weights of a pretrained and finetuned VLA model is surprisingly effective at robust finetuning, and is able to generalize to the finetuning task with different variations, in addition to maintaining generalist abilities. |
|
Reinforcement Learning with Action Chunking Qiyang Li, Zhiyuan Zhou, Sergey LevineNeurIPS, 2025 [website] [paper] [code]
Q-chunking runs RL on a temporally extended action (action chunking) space with an expressive behavior constraint to leverage prior data for improved exploration and online sample efficiency. |
|
Compute-Optimal Scaling for Value-Based Deep RL Preston Fu, Oleh Rybkin, Zhiyuan Zhou, Michal Nauman, Peter Abbeel, Sergey Levine, Aviral KumarNeurIPS, 2025 [paper]
Big models (TD-)overfit less and produce better TD targets, and allows for using bigger batch sizes. We analyze the interplay between model size, batch size, and UTD for scaling value-based RL, and show scaling laws that shows the budget-optimal data-compute tradeoff. |
|
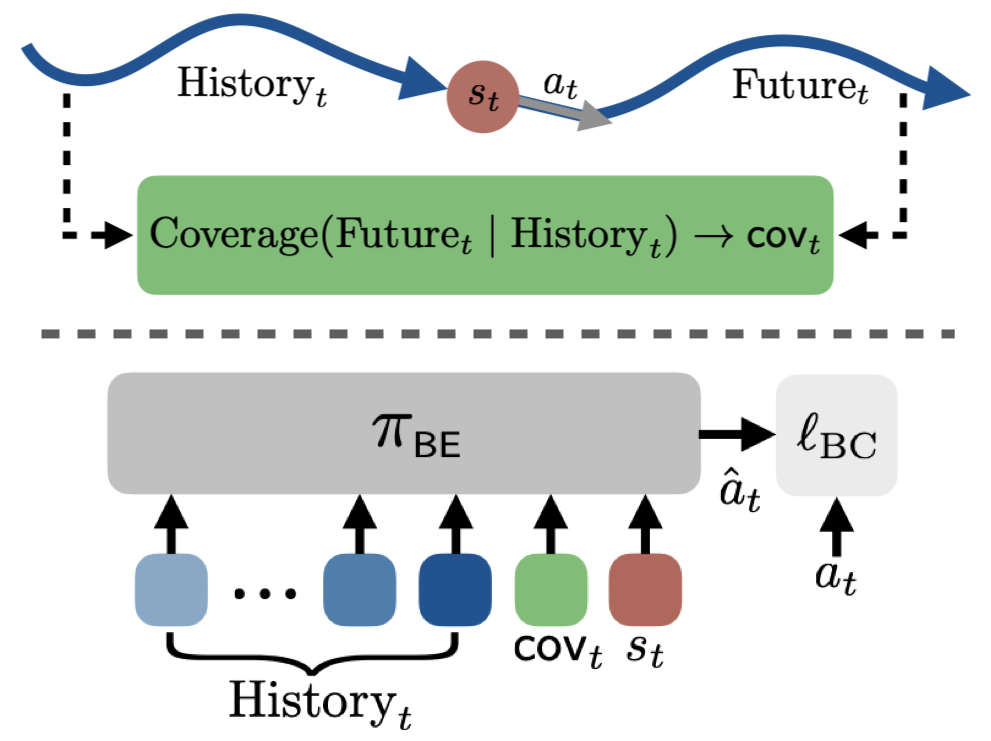
Behavioral Exploration: Learning to Explore via In-Context Adaptation Andrew Wagenmaker, Zhiyuan Zhou, Sergey LevineInternational Conference on Machine Learning (ICML), 2025 [paper]
Behavioral exploration (BE) seeks to train policies that can explore over the space of expert demonstration behaviors. We achieve this by training a long-context policy that's conditioned on history and a notion of "coverage-to-go". |
|
|
AutoEval: Autonomous Evaluation of Generalist Robot Manipulation Policies in the Real World Zhiyuan Zhou, Pranav Atreya, You Liang Tan, Karl Pertsch, Sergey LevineConference on Robot Learning (CoRL), 2025. ICLR Robot Learning Workshop, 2025. (Oral) RSS Robot Evaluation Workshop, 2025. (Best Paper) [website] [paper] [code] Evaluating generalist robot policies is very time consuming. We propose AutoEval, a system that autonomously evaluates generalist policies in the real world with learned success detectors and reset policies. We open access to two AutoEval stations for researchers to evaluate their policies. Submit your policy for evaluation in minutes! |
|
Learning Transferable Sub-Goals by Hypothesizing Generalizing Features Anita de Mello Koch, Akhil Bagaria, Bingnan Huo, Zhiyuan Zhou, Cameron Allen, George KonidarisAAAI Workshop on Generalization in Planning, 2025. (Oral) [paper]
How do we transfer low level skills in hierarchical RL to make it sample efficient, especially in the context of one-shot and few-shot learning? We find that we can learn subgoals classifiers that transfer to unseen tasks with an ensemble of classifiers that focus on diverse features. |
|
|
Efficient Online Reinforcement Learning Fine-Tuning Need Not Retain Offline Data Zhiyuan Zhou*, Andy Peng*, Qiyang Li, Sergey Levine, Aviral KumarInternational Conference on Learning Representations (ICLR), 2025 [website] [paper] [code]
Can we finetune policies and values from offline RL *without retaining the offline data*? Current methods require keeping the offline data
for stability and performance, but this make RL hard to scale up when the offline dataset gets bigger and bigger. Turns out a simple recipe, Warm-start RL, is able to finetune rapidly without data retention! |
|
|
Autonomous Improvement of Instruction Following Skills via Foundation Models Zhiyuan Zhou*, Pranav Atreya*, Abraham Lee, Homer Walke, Oier Mees, Sergey LevineConference on Robot Learning (CoRL), 2024. [website] [paper] [code] [dataset]
Can robots self-improve by collecting data autonomously🤖? We introduce SOAR, a system for large-scale autonomous data collection 🚀 and autonomous improvement📈of a multi-task language-conditioned policy in diverse scenes without human interventions . |
|
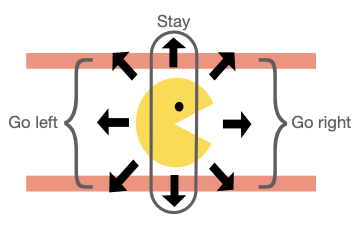
Tiered Reward: Designing Rewards for Specification and Fast Learning of Desired Behavior Zhiyuan Zhou, Shreyas Sundara Raman, Henry Sowerby, Michael LittmanReinforcement Learning Conference (RLC), 2024. [website] [paper] [code] [thread]
Do you need a reward function for your goal-reaching task? Use Tiered Reward! We prove that Tiered Reward guarantees to lead to an optimal policy, and show that it can lead to fast learning in various deep and tabular environments. |
|
Characterizing the Action-Generalization Gap in Deep Q-Learning Zhiyuan Zhou, Cameron Allen, Kavosh Asadi, George KonidarisMultidisciplinary Conference on Reinforcement Learning and Decision Making (RLDM), 2022. [paper] [poster] [code] We introduce a way to evaluate action-generalization in Deep Q-Learning using an oracle (expert knowledge of action similarity), and shows that DQN's ability to generalize over actions depends on the size of the action space. |

|
Designing Rewards for Fast Learning Henry Sowerby, Zhiyuan Zhou, Michael LittmanMultidisciplinary Conference on Reinforcement Learning and Decision Making (RLDM), 2022. (Oral) [paper] [poster] [oral at RLDM at 1:20:00] What kind of reward functions make RL fast? We advocate for rewards with big action gaps and small "subjective discounts". We present an algorithm to design these rewards. |
|
Policy Transfer in Lifelong Reinforcement Learning through Learning Generalizing Features Zhiyuan Zhou (Advisor: George Konidaris)Undergraduate Honors Thesis, Brown CS, 2023. [pdf] [code]
Introduces an approach to learn state features that generalize across tasks drawn from the same distribution. We use an attantion mechanism to learn an ensemble of minimally overlapping state features, leading to an ensemble of policies. We then use a bandit algorithm to learn to identify the generalizing feature in the ensemble and capitalize on that to learn a transferable policy. |